Course
Give your AI a permanent memory of your business. A course for people who use ChatGPT or Claude daily.Compound Context
Geodd logo

Geodd

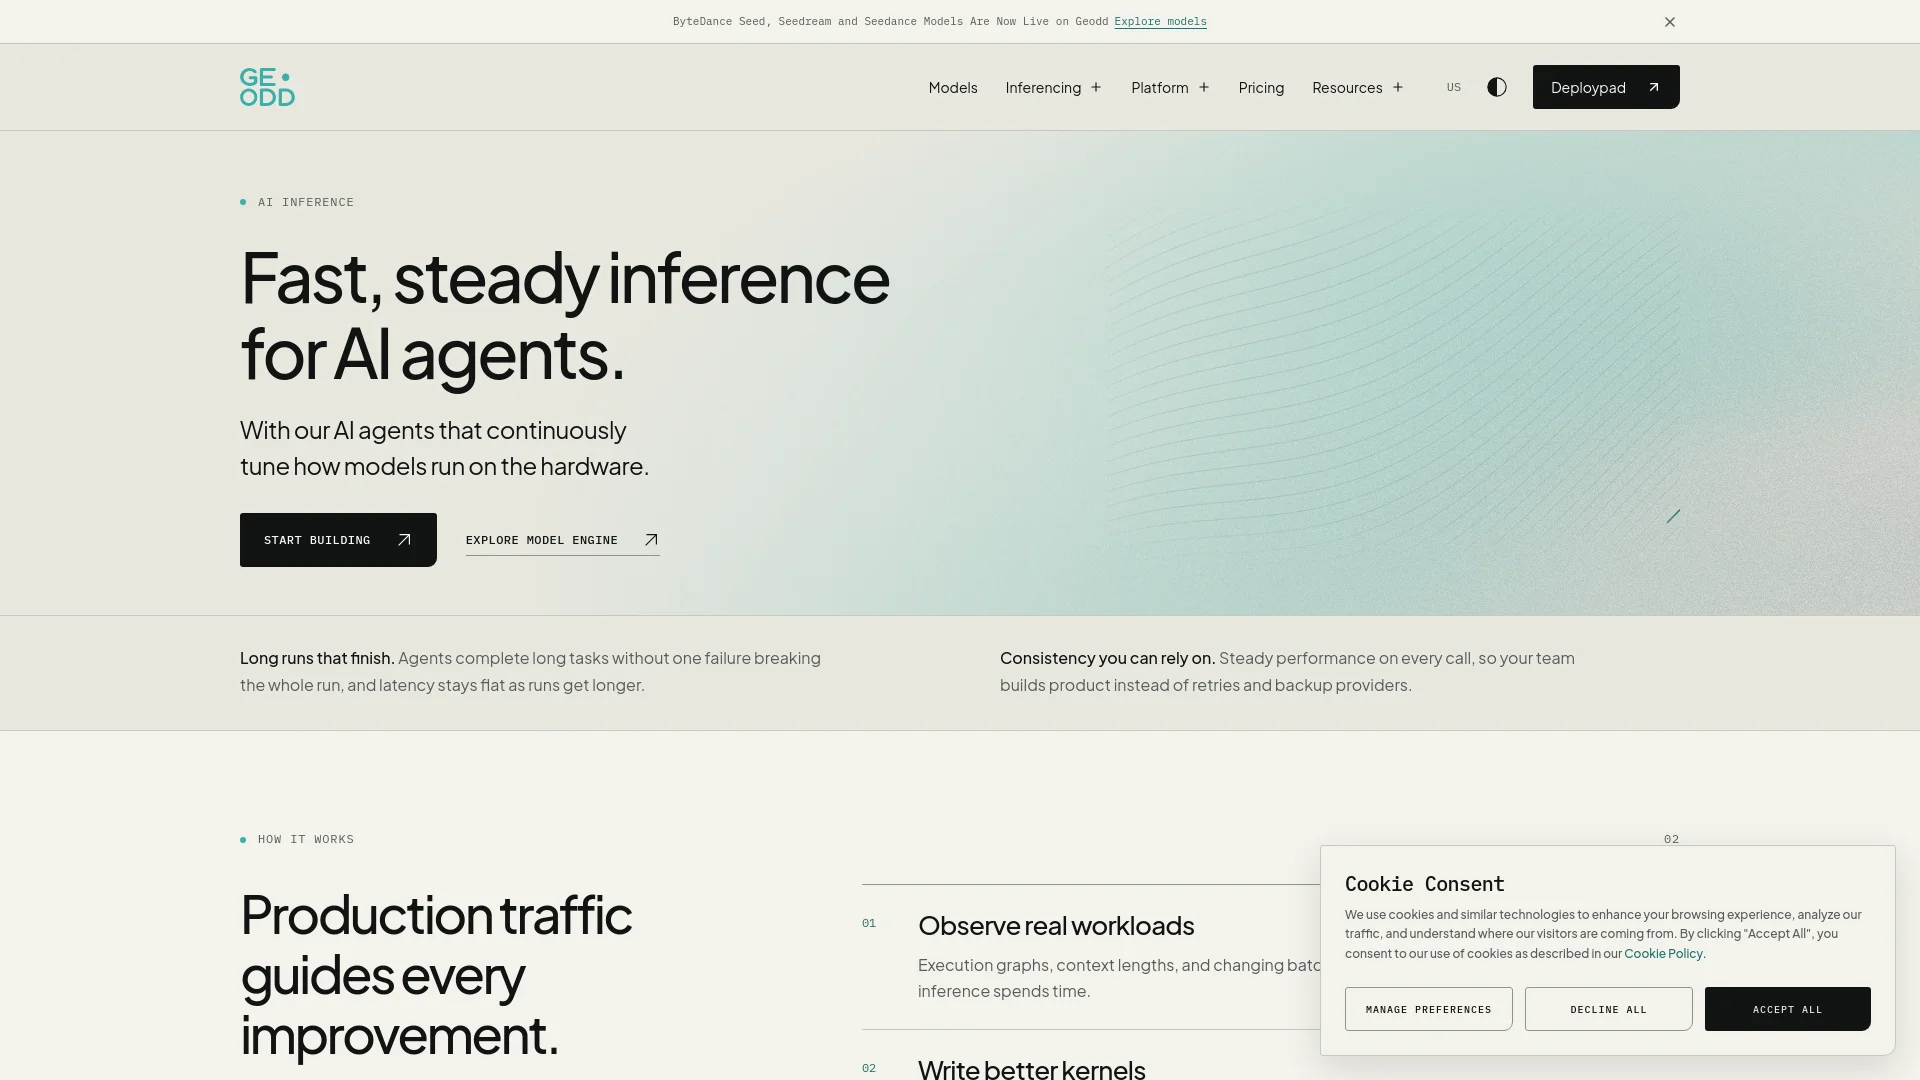
Geodd provides fast, steady AI model hosting through serverless inference and dedicated GPUs. It supports OpenAI-compatible tools, regional deployment, usage tracking, and models built for long tasks.

About Geodd

Who It's For

Geodd is for teams running AI models in real products. It fits developers who need reliable inference, long-running agent tasks, or dedicated GPU capacity without building all the hosting systems themselves.

What You Get

You get serverless access to supported models, dedicated GPU deployments, and one API for both options. Geodd supports OpenAI SDKs, shows token usage, offers US and EU regions, and lists privacy features such as zero data retention. Its tools also improve model performance for NVIDIA, AMD, and Tenstorrent hardware.

How It Works

Geodd studies real workloads to find slow parts of model inference. Its hardware-focused AI models write and improve GPU code, then test those changes against the same workloads. Verified improvements are deployed and measured in production. You can connect through the OpenAI SDK by changing the API base URL.
Stay in the loop

Weekly roundup of new AI agents. No spam, unsubscribe anytime.

Subscribe and get the free 2026 AI Agents Field Guide

Join 1,500+ AI builders ยท weekly, no spam

Features & Capabilities

๐Ÿš€ Production Inference Performance

Reliable Long-Running Execution

Completes extended agent and inference tasks without a single failure interrupting the run.

Consistent Low Latency

Maintains steady performance across repeated calls and longer workloads.

Production-Driven Optimization

Uses real traffic patterns, execution graphs, context lengths, and batch sizes to identify inference bottlenecks.

โš™๏ธ Automated Kernel Optimization

AI-Generated Hardware Kernels

Uses hardware-specific language models to generate and refine optimized inference kernels.

Workload-Based Testing

Validates correctness and measures kernel improvements under the workloads that exposed bottlenecks.

Continuous Performance Loop

Deploys verified improvements, monitors production impact, and feeds results into future optimization cycles.

๐Ÿง  Hardware-Specific Model Engineering

NVIDIA CUDA Optimization

Mosaic provides kernel development for NVIDIA GPUs using CUDA.

AMD ROCm Optimization

Druze is designed for kernel development on AMD GPUs using ROCm.

Tenstorrent Optimization

Strata targets Tenstorrent accelerators and the TT-Metalium software stack.

โ˜๏ธ Serverless and Dedicated Deployment

Serverless Model APIs

Provides hosted access to supported language models with usage-based token pricing.

Dedicated GPU Compute

Offers dedicated GPU infrastructure for demanding production inference workloads.

Multi-Regional Deployment

Supports deployment across US and EU regions, with additional regional expansion underway.

Unified API Access

Uses one SDK for both serverless inference and dedicated compute deployments.

๐Ÿ”’ Enterprise Security and Privacy

Data Isolation

Provides isolated infrastructure and enterprise-oriented workload security.

Zero Data Retention

Supports a zero-data-retention privacy option for inference requests.

GDPR Readiness

Offers GDPR-ready infrastructure with SOC 2 compliance listed as pending.

๐Ÿ”— Developer Integration

OpenAI SDK Compatibility

Works with the OpenAI SDK through a compatible API and base URL.

One-Line Provider Switching

Allows applications to switch providers by changing the API endpoint.

Usage Observability

Provides real-time token usage visibility for inference requests.

Screenshots

See Geodd in action

Use Cases

Optimizing Production Inference Performance

AI infrastructure and platform teams need to improve inference speed and reliability under real production workloads without relying on repeated manual kernel tuning. Geodd observes execution graphs, context lengths, and batch-size changes, then uses hardware-specific AI agents to generate, test, deploy, and measure optimized kernels in serving environments.

AI Infrastructure and Cloud ComputingFor: ML Infrastructure Engineer

Running Reliable Long-Horizon AI Applications

Teams building agentic applications and long-context workflows need inference runs that remain stable as tasks become longer and more complex. Geodd provides production-grade model serving with flat latency, reliable execution, and access to models supporting million-token context windows.

Generative AI and B2B SaaSFor: AI Application Developer

Migrating Inference Providers Without Application Rewrites

Engineering teams may want better inference performance or pricing but face the risk and effort of changing provider integrations. Geoddโ€™s OpenAI-compatible API and unified SDK let developers switch providers by changing the API base URL while retaining existing application code and gaining token usage observability.

Software and TechnologyFor: Platform Engineer

Deploying Privacy-Conscious Enterprise Inference

Organizations processing sensitive prompts and model outputs need regional infrastructure, data isolation, and stronger control over logging and retention. Geodd supports US and EU deployments with GDPR-ready infrastructure, zero data retention options, and enterprise-oriented workload isolation for production inference.

Enterprise Technology and Regulated IndustriesFor: IT Infrastructure and Security Leader

Scaling Dedicated AI Inference Capacity

Companies with demanding or predictable AI workloads need more control and capacity than shared serverless endpoints provide, while avoiding the operational burden of self-hosting GPUs. Geodd offers dedicated GPUs and isolated inference environments backed by regional capacity, enabling teams to provision production model servers and scale reliably.

AI Infrastructure and Cloud ComputingFor: ML Platform or Cloud Infrastructure Team